Microsoft 365 outage recovery not going as expected cause explained November 2026 is exactly what millions of frustrated users searched for on November 12, after Microsoft’s own fixes failed to stick. Thursday afternoon, Outlook, Teams, SharePoint, and Copilot all buckled at once. Offices went dark. Hospitals switched to phone calls. Even a county jail in Colorado couldn’t process bond payments by email.
Here’s the uncomfortable truth: Microsoft tried to fix it, said so publicly, and then had to admit the fix didn’t work. That’s rare, and it’s why this incident is getting so much attention.
Quick Overview:
- What happened: A widespread Microsoft 365 outage hit Exchange Online, Teams, SharePoint, Copilot, and Defender XDR starting around midday Eastern on November 12, 2026.
- Why recovery stalled: Microsoft’s first and second rounds of fixes — server restarts and traffic rerouting — didn’t resolve the “elevated load” issue, forcing a longer, multi-stage recovery.
- Scale: Downdetector logged over 130,000 user reports in under an hour for Outlook, Teams, Copilot, and the Microsoft Store.
- Who got hit hardest: Businesses, schools, government agencies, and hospital systems that depend on Microsoft 365 as their single communication backbone.
- Status today: Services were restored in stages over several hours, with Microsoft issuing repeated “not as expected” updates before stabilizing things overnight.
What Actually Happened on November 12, 2026
Picture a highway that suddenly gets ten times its normal traffic. That’s basically what hit Microsoft’s backend. The company said part of its infrastructure was “experiencing elevated load across multiple regions”.
Translation: too many requests, not enough capacity to handle them cleanly. Something — possibly a misbehaving client, a backend service, or an authentication loop — was hammering the system harder than normal traffic patterns would predict.
By early afternoon, Downdetector showed over 130,000 reports in a single 45-minute window for Outlook, Teams, Copilot, and the Microsoft Store. Real organizations felt it immediately. Unity Health in Toronto told patients to call instead of email. Penn State reported its planning and AI tools going dark. An Arapahoe County, Colorado sheriff’s office said jail staff couldn’t process bond payments because email was unreachable.
That’s not an inconvenience. That’s operations grinding to a halt.
Microsoft 365 Outage Recovery Not Going As Expected: The Timeline
This is where it gets interesting — and where the “recovery not going as expected” part of this story actually lives.
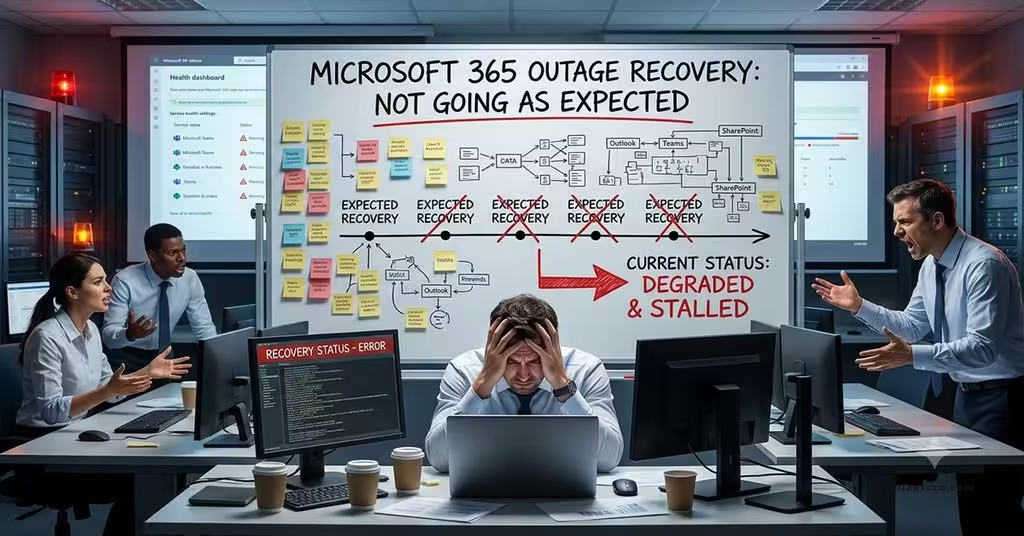
Around 5 p.m. Eastern, Microsoft posted that it was “opening all available pathways to restore service,” adding that “actions taken thus far have not provided the anticipated relief”. That’s corporate-speak for: our first fix didn’t work.
Then, at 10:13 p.m., Microsoft posted again. The changes it had made were “not taking as expected”. Two admissions, hours apart, that the recovery plan wasn’t going to script. In my experience watching these status-page sagas, that kind of repeated walk-back almost always signals the root cause is more layered than the first diagnosis suggested.
Why the Fixes Kept Failing
Microsoft’s engineering notes described two concrete recovery actions: restarting affected servers and redistributing traffic across its global infrastructure to spread out the load. Both are standard playbook moves. Neither fully worked on the first attempt.
Dr. Timothy Wood, a computer science professor at George Washington University, offered a theory that’s stuck with a lot of IT folks since: the outage might not have been the servers themselves failing, but the monitoring system that checks server health malfunctioning instead.
“The thermometer is broken,” Wood said, “and anyone you test looks like they have a fever”.
That’s the fresh way to think about this. If your health-check system is lying to you, every fix you deploy gets evaluated against bad data. You restart a server, your monitoring says it’s still sick, so you restart it again — except it was never actually broken. You’re chasing a ghost while real capacity problems pile up elsewhere.
Is that confirmed as the single cause? No — Microsoft didn’t publish a full root cause analysis in the first 24 hours, and professional opinion here is clearly flagged as professional opinion, not an official Microsoft finding.
Common Mistakes & How to Fix Them During Microsoft 365 Outage Recovery
When the Microsoft 365 outage recovery wasn’t going as expected, plenty of IT teams made the situation worse for themselves. Here’s what I’d flag, and what to do instead.
Mistake 1: Waiting silently instead of switching communication channels. Fix: The moment Outlook or Teams flags issues, pivot immediately to SMS, a phone tree, or a backup tool like Signal or Slack for anything time-sensitive.
Mistake 2: Repeatedly refreshing or re-logging-in. Fix: Stop. Hammering a struggling authentication system with retry attempts adds load exactly where it’s already strained. Walk away for 15 minutes.
Mistake 3: Assuming it’s just your device or network. Fix: Check the official Microsoft 365 status page or a third-party tracker like Downdetector before troubleshooting your own hardware for an hour.
Mistake 4: No offline fallback for critical documents. Fix: Keep local copies of anything business-critical — contracts, schedules, payment records — synced but also saved locally, not solely cloud-dependent.
Mistake 5: Blaming your IT department. Fix: This one’s on Microsoft’s infrastructure, not your internal network team. Save the frustration for the right target.
Step-by-Step Action Plan for Beginners During a Microsoft 365 Outage
If you’re new to dealing with cloud-service outages, here’s what I’d actually do, in order:
- Confirm it’s a real outage. Check Microsoft’s official status page and Downdetector before assuming it’s your Wi-Fi.
- Switch communication immediately. Text, call, or use a secondary messaging app for anything urgent.
- Pause automated workflows. If you’ve got Power Automate flows or scheduled Teams messages tied to Microsoft 365, pause them to avoid error cascades once service returns.
- Document what broke. Screenshot errors and timestamps — useful for insurance, SLAs, or internal reporting later.
- Wait for staged recovery, not instant fixes. Large-scale cloud outages rarely resolve in one shot; expect Microsoft to roll fixes out region by region.
- Re-verify data integrity after restoration. Once services return, check for duplicate emails, missing calendar invites, or sync errors — common side effects of forced restarts.
- Build a lightweight continuity plan going forward. Even a one-page “what do we do if Microsoft 365 goes down” doc saves real chaos next time.
Microsoft 365 Outage Recovery: Expected vs. What Actually Happened
| Recovery Stage | What Microsoft Expected | What Actually Happened |
|---|---|---|
| Initial server restarts | Quick restoration of affected nodes | Partial relief only; load issues persisted |
| Traffic redistribution (~5 p.m. ET) | “Anticipated relief” across regions | Microsoft admitted actions “have not provided the anticipated relief” |
| Secondary fix attempt (~10 p.m. ET) | Changes to stabilize infrastructure | Microsoft reported changes “not taking as expected” |
| Overnight stabilization | Full service restoration | Gradual, staged recovery into the following day |
Why This Keeps Happening to Cloud Platforms
Here’s the thing — this isn’t really a Microsoft problem. It’s a centralization problem. When hundreds of millions of people depend on one authentication layer, one hiccup ripples everywhere at once.
The U.S. Cybersecurity and Infrastructure Security Agency has repeatedly flagged cloud service concentration as a systemic risk for exactly this reason. One company’s bad Thursday becomes everyone else’s bad Thursday too.
Is there a way to fully outage-proof your business against this? Not really — not unless you want to run parallel infrastructure, which most small and mid-size businesses simply can’t afford. What you can do is build redundancy into your communication habits, not your tech stack.
Key Takeaways
- The November 12, 2026 Microsoft 365 outage hit Exchange Online, Teams, SharePoint, Copilot, and Defender XDR simultaneously.
- Microsoft’s infrastructure experienced “elevated load across multiple regions,” and the company’s first two recovery attempts didn’t deliver the expected results.
- Microsoft publicly admitted its fixes weren’t “taking as expected” — a rare and notable transparency moment.
- A GWU professor’s theory suggests a faulty health-monitoring system, not the servers themselves, may have driven the confusion.
- Over 130,000 user reports hit Downdetector within less than an hour, spanning Outlook, Teams, Copilot, and the Microsoft Store.
- Hospitals, government offices, and universities all reported real operational disruptions, not just inconvenience.
- The best defense isn’t avoiding Microsoft 365 — it’s having a fast, low-tech fallback plan ready before the next outage hits.
If you run a business, a school, or anything in between, the lesson from this Microsoft 365 outage recovery not going as expected cause explained story isn’t “switch platforms.” It’s “stop treating your cloud suite as unbreakable.” Build the fallback plan now, while things are calm, so the next status-page spiral doesn’t catch you flat-footed.
FAQs
Did Microsoft ever release an official root cause for the November 2026 outage?
Microsoft confirmed “elevated load across multiple regions” and acknowledged its fixes weren’t producing expected results, but a full, detailed root cause analysis wasn’t published within the first 24 hours.
How long did the Microsoft 365 outage recovery actually take in November 2026?
Recovery happened in stages, starting with server restarts and traffic redistribution in the afternoon, continuing through additional fix attempts into the night, with most services stabilizing by the next day.
Was this November 2026 Microsoft 365 outage caused by a cyberattack?
Nothing in Microsoft’s public statements pointed to a cyberattack. The language used — elevated load, infrastructure strain, traffic redistribution — points toward a capacity or monitoring issue rather than malicious activity.